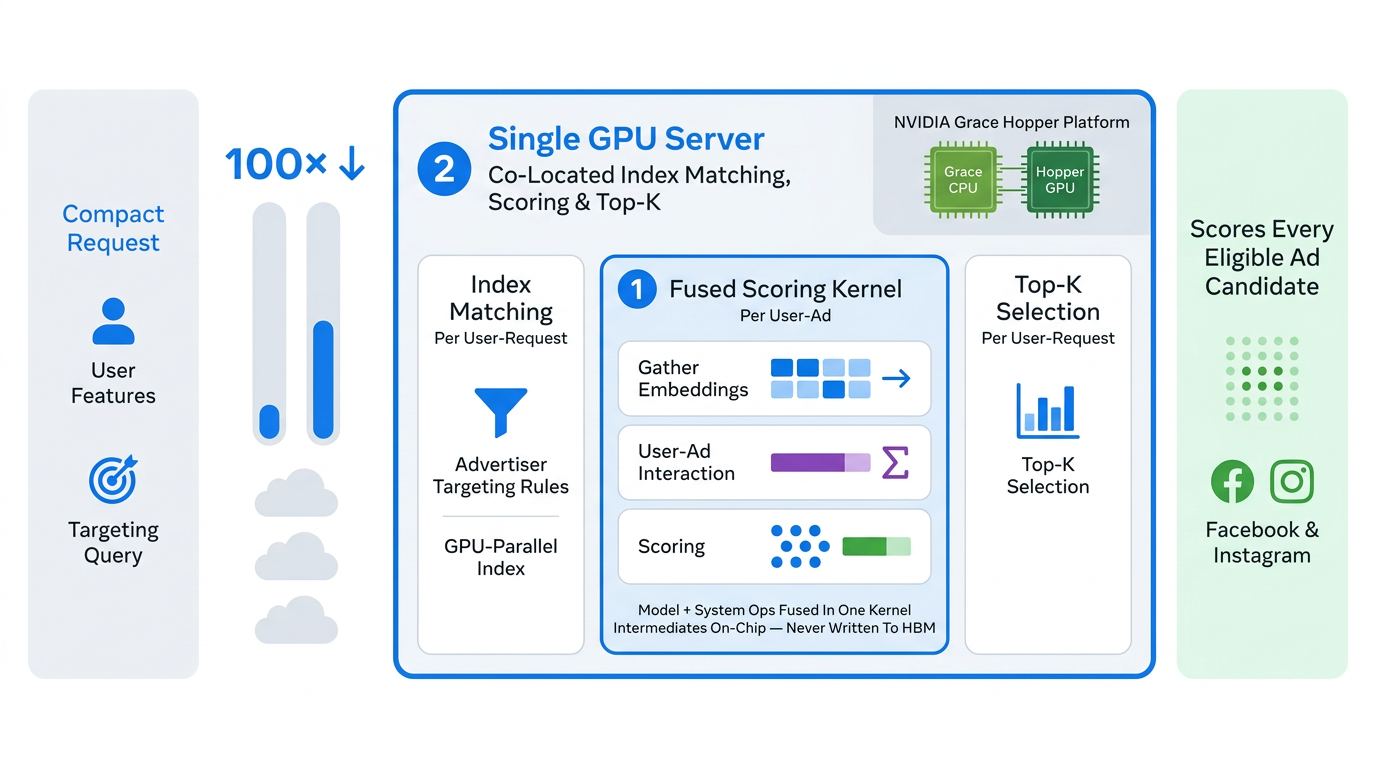
Figure 2: System architecture of the single fused GPU pipeline for Meta Andromeda. This pipeline co-locates index matching, fused scoring, and top-K selection on a single GPU server. The fused scoring kernel executes the entire per-user-ad computation — from embedding gathering to MoE interaction and scoring — in a single on-chip pass, keeping intermediate results in registers and shared memory to eliminate HBM bottlenecks. This co-design reduces network traffic by approximately 100x by sending only compact request payloads — surpassing 1 billion ads per second while scoring every eligible ad across Facebook and Instagram.
Figure 2: System architecture of the single fused GPU pipeline for Meta Andromeda. This pipeline co-locates index matching, fused scoring, and top-K selection on a single GPU server. The fused scoring kernel executes the entire per-user-ad computation — from embedding gathering to MoE interaction and scoring — in a single on-chip pass, keeping intermediate results in registers and shared memory to eliminate HBM bottlenecks. This co-design reduces network traffic by approximately 100x by sending only compact request payloads — surpassing 1 billion ads per second while scoring every eligible ad across Facebook and Instagram.
Meta believes in building community through open source technology. Explore our latest projects in Artificial Intelligence, Data Infrastructure, Development Tools, Front End, Languages, Platforms, Security, Virtual Reality, and more.
ANDROID
iOS
WEB
BACKEND
HARDWARE
Allow the use of cookies by Meta on this browser?
We (Meta Platforms Ireland Limited) use cookies on this site. Some of these are essential cookies which are required for the site to work as intended. We also use optional cookies to perform site analytics and measure the performance of content on this site. You have control over the optional cookies that we use. If you choose to "Decline optional cookies", you can continue to use the site but we will be unable to perform site analytics on this site using such cookies and similar technologies. Learn more about our cookies and third-party providers in our Cookies Notice, or you can review or change your choices, including withdraw your consent, at any time in your Settings page.