Last year, we introduced GEM, the industry’s largest recommendation system (RecSys) foundation model. GEM established Meta’s first LLM-inspired paradigm for ads recommendation, driving major performance gains. Building on this foundation, our next goal is to further scale both compute and intelligence transfer with next-generation hardware, and expand this capability across Meta’s entire ads ecosystem. This spans dozens of surfaces and objectives, delivering seamless full-funnel optimization across awareness, consideration, and conversions.
The 2026 generation of GEM shifts from isolated per-domain optimizations — such as Facebook, Instagram, Reels — to a single central foundation model. It learns from data and signals across all of Meta’s ads platforms, bends the scaling curve at LLM-scale computation, and delivers strong advertiser outcomes through post-training techniques that provide a larger latency budget without requiring real-time evaluation of all ad candidates — all on a substantially more efficient training stack. The result is simultaneous ad performance gains across every surface and funnel stage, and deeper understanding that better matches ads to what people are looking for.
GEM has delivered 18.9% conversion improvement and 12% ad click-through rate (CTR) improvement across Meta’s ad surfaces and objectives, and additionally contributed 5.8%, 4.1%, and 1.6% conversion uplift on Facebook, Instagram, and off-site conversion for targeted users over the past year. These gains span both upper-funnel surfaces and deep-funnel optimization goals, driving stronger returns for advertisers.
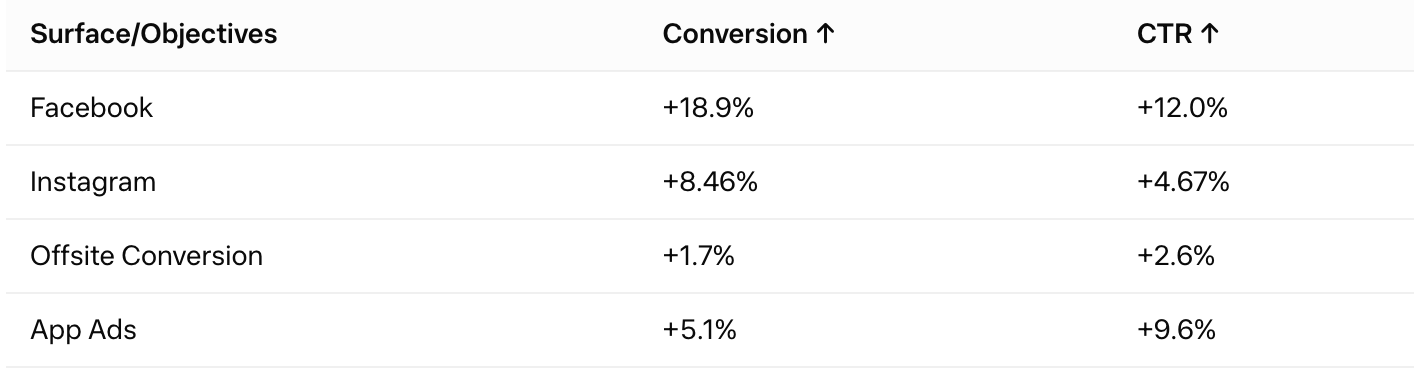
GEM advances the frontier of recommender systems in the following four areas:
1. Bending the Scaling Curve, Enabling 2.5x Model Complexity
Challenge: Empirical scaling laws demonstrate that model performance predictably improves with compute, parameter, and data size using transformer model architecture. However, recommender system models do not exhibit similar scaling properties with transformer due to massive heterogeneous features and shifting distributions.
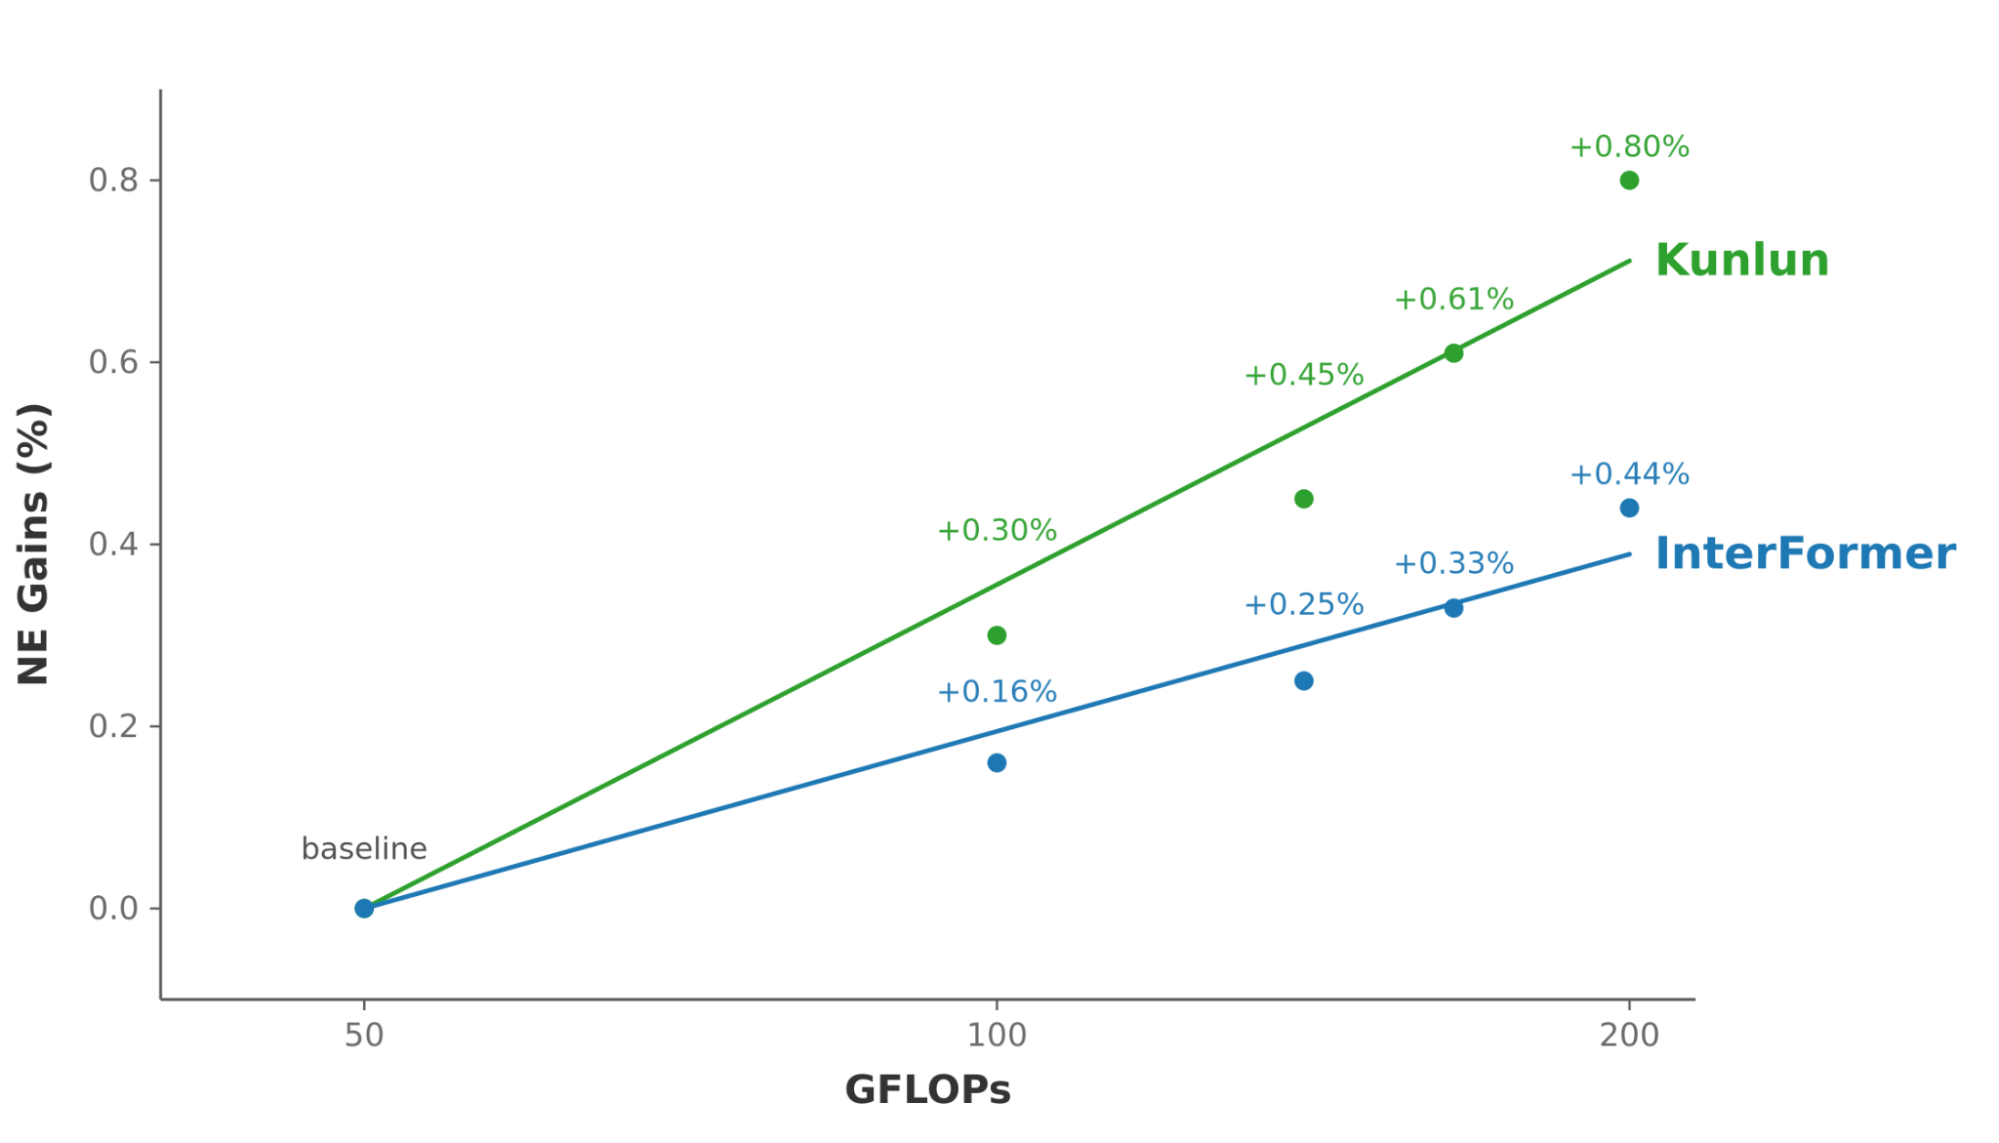
Solution: We built an LLM-style architecture — Kunlun, co-designed with the latest GPU hardware, to make larger, deeper models substantially more cost-efficient and to enable long-context learning over user engagement history. We observed an LLM-like scaling law at our largest pre-training scale with 2.5x model complexity growth from earlier versions of GEM. The pattern mirrors frontier LLMs: more capacity and longer context produce emergent gains in ranking quality that translate directly into business results.
2. Efficient Intelligence Transfer From GEM to User-Facing Models
Challenge: Serving a model at this scale in real time is prohibitively expensive and drives up latency, compromising both user experience and advertiser ROI.
Solution: The structured representation, LoopFM, a state-of-the-art post-training technique, transfers GEM’s internal representations and sequential historical memory to downstream models. Through computation sharing, it doubles the intelligence transfer together with the knowledge distillation deployed in the previous version, at no additional compute cost or latency. We also introduced elastic pre-computation (Solaris) to harvest the gains from the upstream model.
3. Accelerating the Central Compute Engine With Large-Scale Cross-Surface, Cross-Domain Learning at Meta Ads Scale
Challenge: Meta’s apps span dozens of surfaces — Facebook, Instagram, Reels, Stories, and more — with 3.6 billion people using at least one of our apps each day. Each surface and optimization objective previously had its own independent prediction system. As the platform grows in surfaces and objectives, so does the challenge of improving ad performance simultaneously.
Solution: GEM accelerates one single, unified compute engine through the central foundation model that jointly predicts clicks and conversions across all surfaces, including Facebook and Instagram, and across every key advertiser objective from off-site conversions to mobile app installs. The generalizable representations learned on data-rich click tasks transfer into data-sparse conversion tasks. A new training recipe with cost-free data mixing and the domain expert framework makes this heterogeneous, large-scale learning tractable, with predictable scale and enhanced reliability.
4. Scaling Total Training FLOPs by 4x While Doubling E2E Training Efficiency Across Thousands of GPUs
Challenge: Training a RecSys foundation model across thousands of GPUs at this scale requires careful orchestration of compute, parallelism, communication, and memory. Today’s data center GPUs and their software stacks are mostly optimized for LLM workloads, whereas recommendation workloads have a fundamentally different profile due to unique data characteristics that make it extremely difficult to achieve high GPU compute utilization while scale.
Solution: We developed custom kernels with low precision and new 5D parallelism strategies co-designed with the latest GPU hardware and Meta’s training cluster, and optimized model architecture with infrastructure together to scale efficiently across thousands of GPUs. End-to-end training efficiency is doubled to 20-25% model FLOPS utilization (MFU) with 4x total training FLOPs, enabling GEM to train at LLM-scale at Meta (see full technical story in our companion blog on Training GEM at LLM Scale).
Scaling Law: Bend Scaling Curve at Frontier Scale with Kunlun
GEM introduces a new LLM-style model architecture — Kunlun. Compared to the previous version (Interformer), Kunlun delivers 2x performance gains with the same computation scaling. Kunlun is designed around the following innovations:
- Standardize and unify architecture framework by seamlessly interleaving lifelong sequence modeling with scalable recommendation-specific cross-interaction.
- Introduce scalable architecture through deep co-design with the latest generation of hardware, and computation reduction with almost no model quality regression.
- Innovate efficient sequence scaling to process longer user engagement contexts with offline sequence infrastructure.
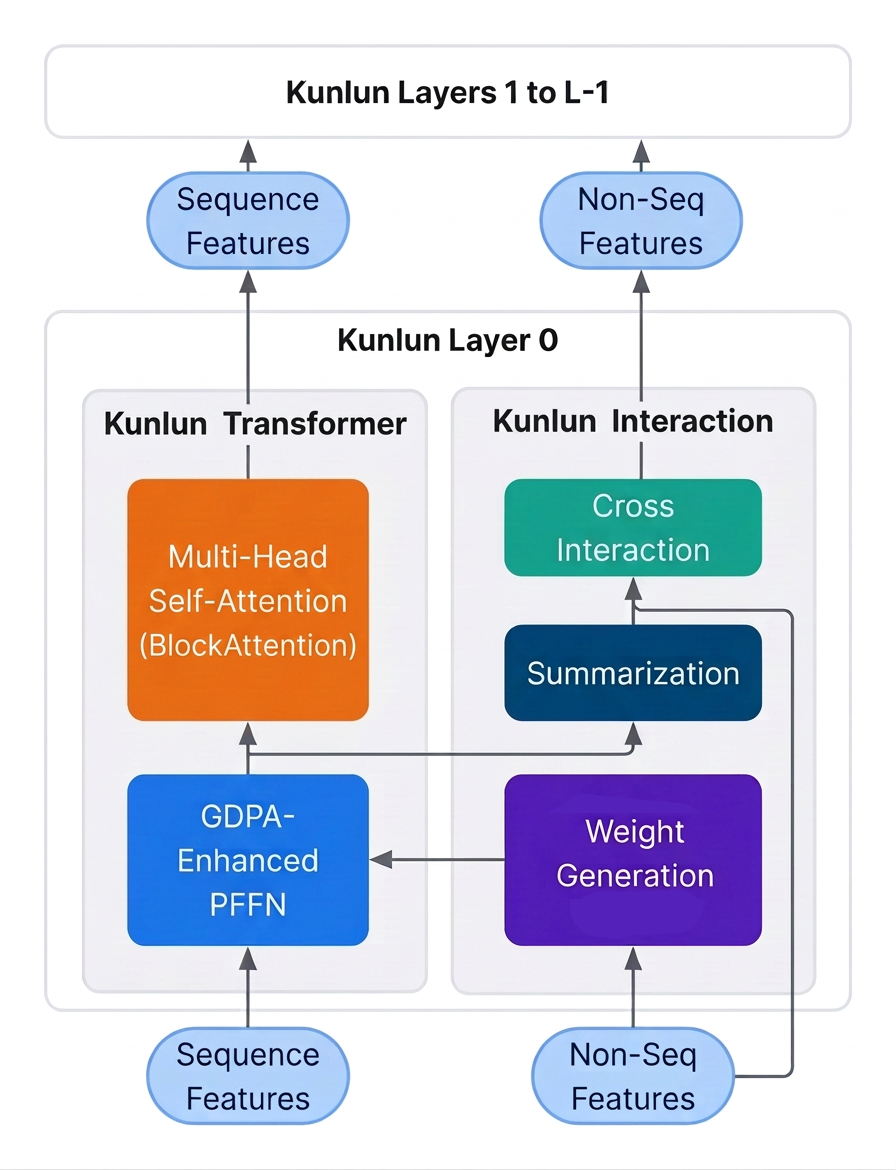
Efficient Architecture for Scaling Recommendations
GEM’s Kunlun architecture effectively bends the recommender system scaling curve at frontier training scales by empowering ultra-long user sequences and massive user-item interaction features. For the following technical discussion, we define two types of features: non-sequence features (such as user demographics, ad content representations), and sequence features with a sequence of events, each composed of a set of features.
This architecture introduces three fundamental advancements:
1. A Standardized and Unified Architecture Framework
We advanced the LLM-style architecture to better capture the unique characteristics of recommender system models — specifically, heterogeneous features and data dynamics.
Each layer consists of:
- Attention: customize the attention and feed-forward networks to capture the long dependency pattern in user behavior by adapting to data dynamics.
- Summarization Component: simplify and enhance the summarization architecture to extract critical user insights from sequences, effectively bridging sequence and non-sequence structure.
- Cross Interaction: expand to the mixture-of-experts (MoE) style design, enabling large-scale modeling of complex interactions between sequence and non-sequence features.
2. Introducing Scalable Architecture Through Deep Co-design
We co-designed the architecture with the latest generation of hardware to allow it to grow deeper and wider efficiently:
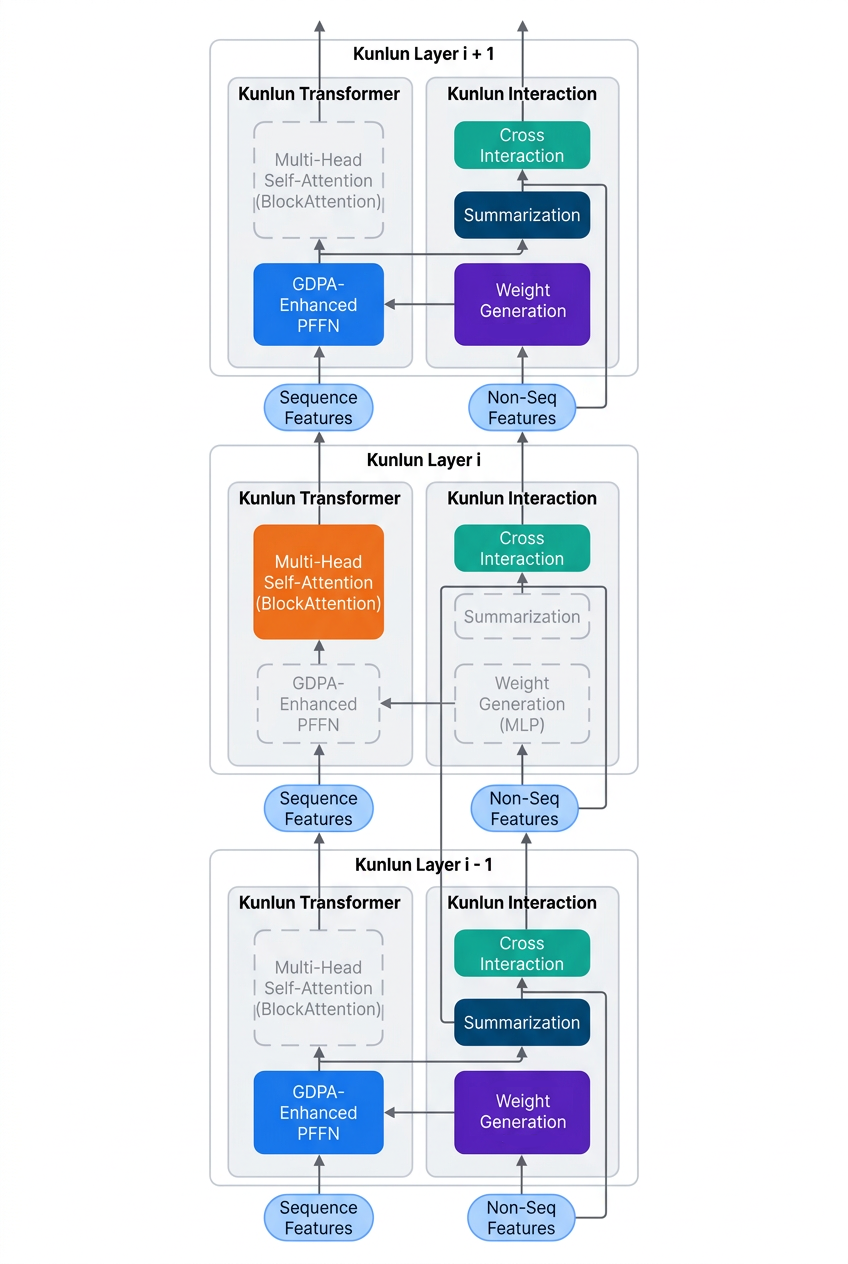
- Computation Complexity Reduction via Block Attention: Replacing full self-attention with block-aligned sparse attention reduces the complexity associated with sequence length from quadratic to linear relative to window size, and uses only the window size that is a multiple of block size, friendly for the kernel without partial block size.
- Component Unification via Architecture Reformulation: Per-Example Feed-Forward Networks (pFFN) was introduced to adapt the traditional FFN to per-example distribution. We reformulated the pFFN component into attention operations through Generalized Dot-Product Attention (GDPA), speeding up training by targeting at unifying the model’s many attention-like operations into a single GPU kernel, delivering up to 2x forward speedup.
- Scalable Cross interaction through Expert Parallelism: Our cross-interaction component utilizes a scalable, MoE-like framework that employs model-expert parallelism, allowing each GPU to process a subset of expert sub-networks in parallel.
3. Innovating Efficient Sequence Scaling
We introduced specialized component designs to make ultra-long sequences computationally tractable:
Component Skip Connection (CompSkip): The computational skip mechanism selectively activates sequence modules in each layer, and only routes outputs through residual connections. By selectively deactivating the specific components, which is based on the assumption that the network can recover quickly after re-activating, we reduce FLOPS by 43% with negligible quality loss.
Sequence Unification (OneSeq): We selectively unify user sequences chronologically after the event feature aggregation. This allows a single, unified sequence layer to process long sequences, even when individual events possess heterogeneous structures and features. In the system, we have different user sequence sources, some of which have different events features. For example, an event in a purchase sequence can be described by ad ID and account ID, while the event in a post sequence is described by actors and object ID. They cannot simply be unified from the data source level due to the different set of event features. It requires the flexible sequence unification approach to maximize GPU efficiency because of large-size tensor operations and minimizing operator fragmentation.
 |
 |
How Ultra-Long Sequences Matter
The new architecture makes ultra-long sequences feasible. GEM scaled the long engagement context length by 2x in production, and further enabled the capability of scaling long context to 25x, demonstrating infrastructure capability at frontier scale. Along the way, we discovered:
- Prediction quality follows a power law with sequence length. The relationship is predictable and consistent across sequence lengths.
- Larger models benefit disproportionately from longer sequences. This creates a virtuous cycle: scaling compute makes the model bigger, which makes longer sequences more valuable. Scaling sequence length makes the model more accurate, which justifies more compute.
- The two scaling laws reinforce each other, offering investment directions to bend the overall scaling law curve beyond simply adding compute.
Post-Training: Knowledge Transfer at Scale
The value of the foundation model depends on how effectively its intelligence transfers to the hundreds of vertical models that serve ads in real time. GEM revolutionizes post training for recommendation systems through the structure representation with the deep historical memory from the central brain, achieving 2x of transfer effectiveness beyond knowledge distillation. Furthermore, async computation is introduced to a few domain-specific foundation models to transfer the knowledge to vertical models.
Structure Representation at Scale
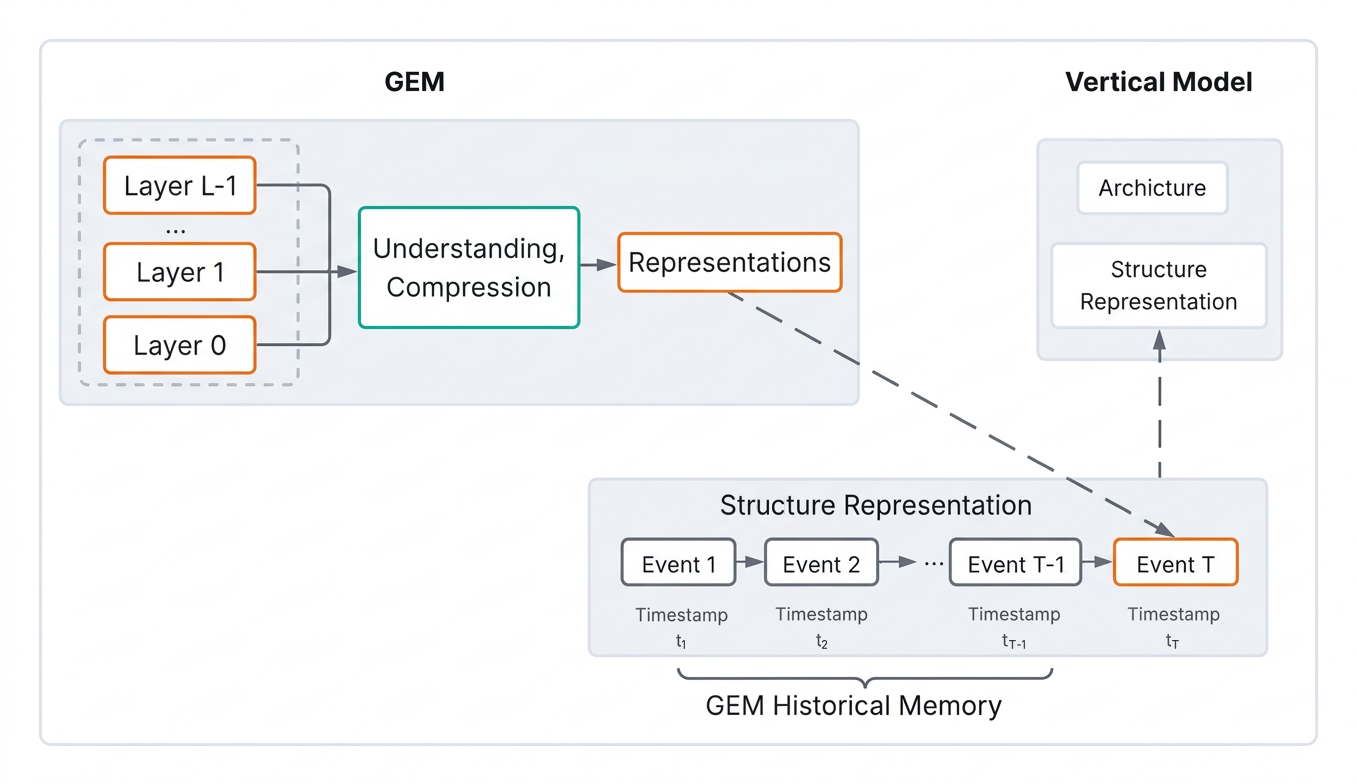
Knowledge distillation is effective but limited in bandwidth: downstream models only receive a compressed view of GEM’s intelligence at each training process. To address the limitation, we introduce the precomputed structure representation, such as LoopFM, to understand and compress the central brain from the foundation model into a compact representation, and then structure it with deep historical memory. It enables the downstream models to learn the long context from our central brain. It consists of the following major components across the system:
- Understand and Compress Intelligence: We compress the intelligence from GEM into the compact representations, which are summarized from the important layers, and used to comprehensively describe the event (or data) that is processed by the foundation model.
- Structure with Deep Historical Memory: We structure its compact representation together with the representations that the foundation model previously generated for the same user into a sequential context window, capturing user intent dynamics across all surfaces and traffic through GEM’s memory.
- Learn from Long Context Intelligence: Downstream models will learn the structure representation with long historical context through the specialized architecture during both inference and training time.
The representation generation process is precomputed and shared with the computation to generate soft labels of the foundation model for knowledge distillation without additional foundation model cost.
Speculative Precomputation for Fresh Predictions
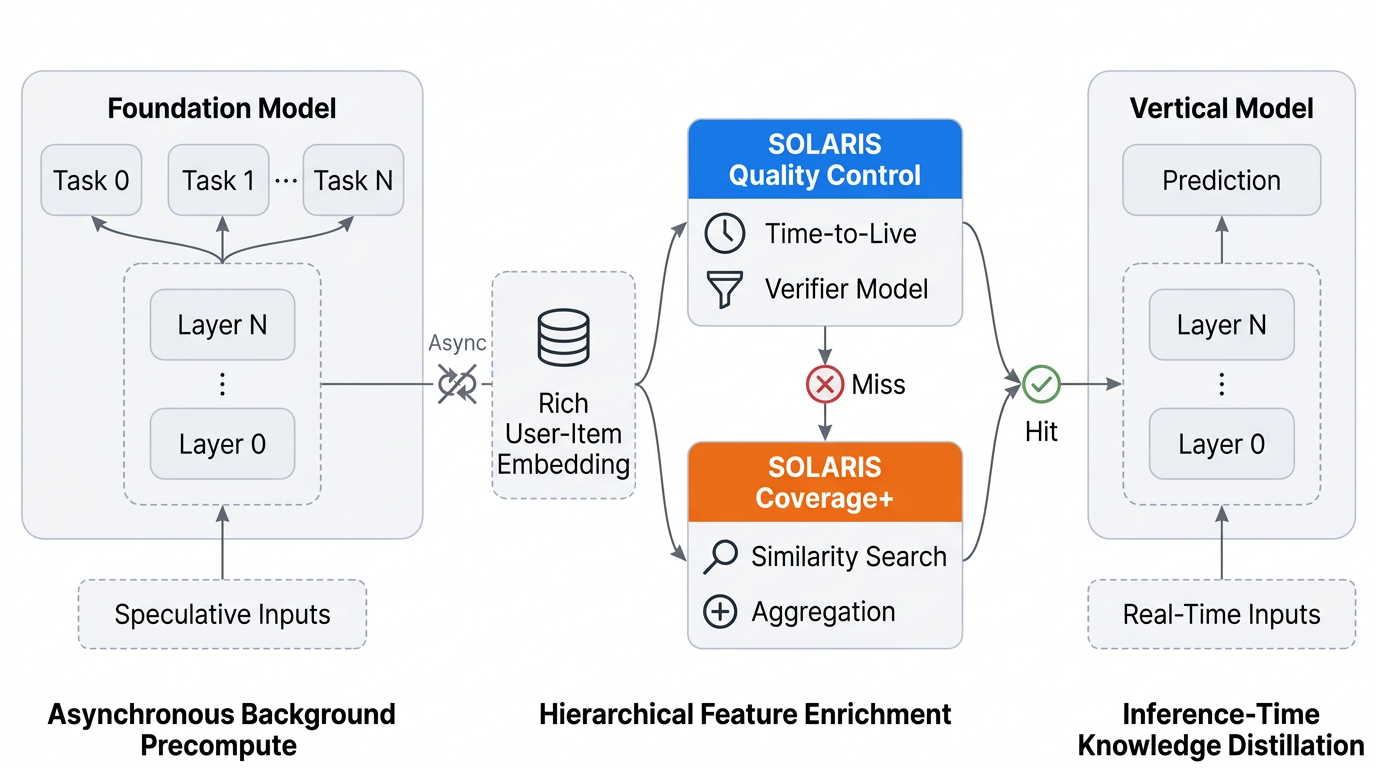
Solaris keeps knowledge transfer fresher, precomputing the user-ad representation from GEM just before vertical model inference needs it. Evaluating the large-scale model inside a live ad request is not affordable, Solaris moves it in time: It speculatively precomputes foundation model embeddings for the user-ad pairs a future request is likely to need, and delivers them just-in-time on the serving hot path. Downstream models gain access to near-real-time foundation model intelligence without being constrained by the latency. Borrowing the idea of speculative decoding from LLM serving, Solaris works through the following major components across the system:
- Deliver Fresh Runtime Knowledge: It generates the user-ad embedding directly, giving vertical models real-time, point-to-point knowledge of how a specific user is likely to act on the exact ad candidate.
- Speculate Ahead of the Request: As multi-stage ranking narrows a live request down to its top ad candidates, Solaris evaluates those user-ad pairs with the foundation model in asynchronous background jobs. The computation carries no latency budget with elastic capacity while it can capture rich knowledge.
- Enrich Coverage Hierarchically: When an exact user-ad embedding is unavailable, the system degrades rather than drops. It substitutes an aggregate of the user’s own recent embeddings across the same ad groups, or borrows from behaviorally similar users.
Large-Scale Cross-Domain Optimization: Optimize Across Surfaces and Funnels
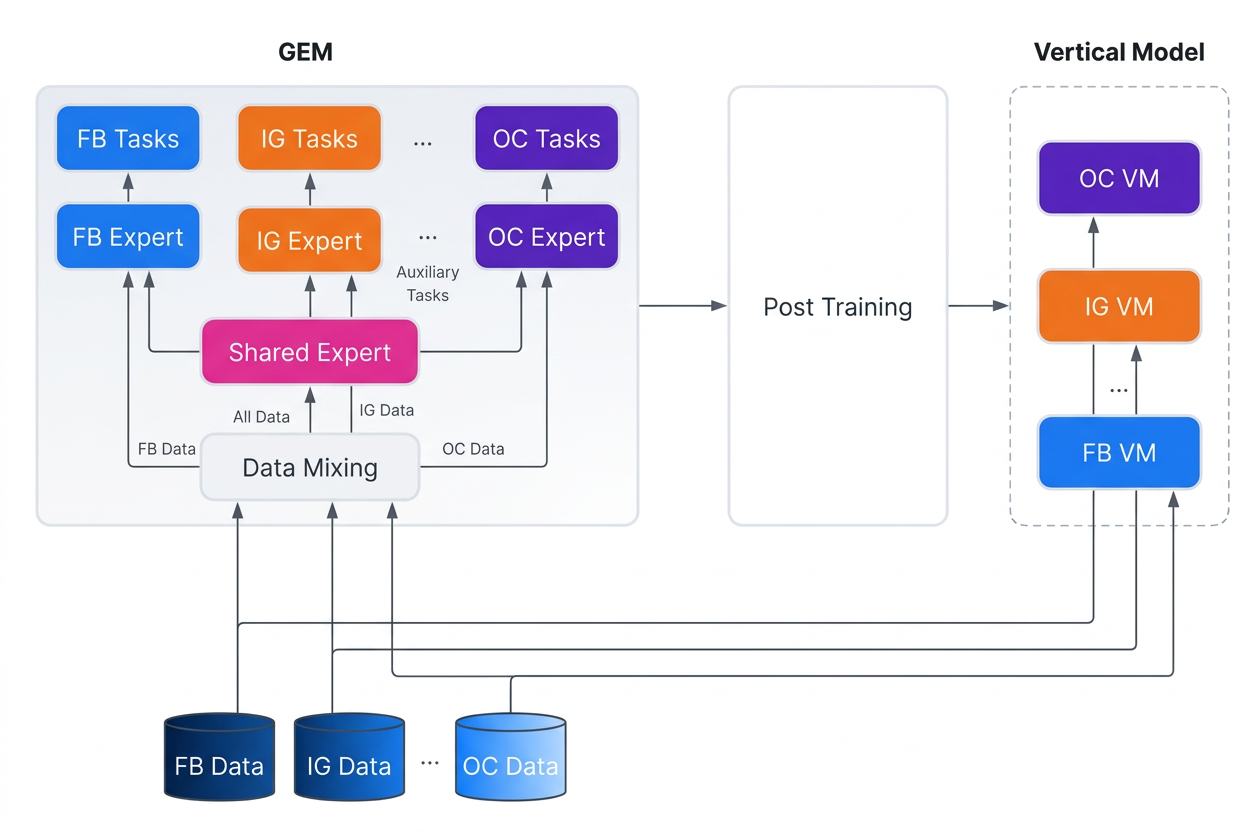
We further trained GEM with the ads data at Meta scale, including all-surface data (e.g., Facebook and Instagram Feed and Reels/video) and deep funnel optimization (e.g., off-site conversion, mobile app install). GEM powers the first optimized model that jointly predicts both CTR across all the surfaces and conversion rate (CVR) across the major optimization goals. Previously, each surface and each prediction objective had its own system. This means learnings from engagement patterns across platforms can more directly be used to understand its conversion behavior (e.g., purchase) across ad surfaces. This positions GEM as the central model and compute engine for ads recommendation across Meta’s advertising surfaces.
Unlike LLMs with the static data, RecSys models need to deal with data dynamics and freshness as well as the diverse distribution across surfaces and traffic. To overcome the challenge, GEM built the first training recipe for the large-scale cross-surface, cross-domain unification through:
A Cost-Free Data Mixing Strategy: It introduced virtual data loading from different combinations of data pipelines without physically merging data together and incurring additional storage cost. It can flexibly adapt to the current ads ecosystem where the downstream models still train with the specific surface or traffic data. We also design a data mixture mechanism to control the mixture proportions during offline and online training close to the real datastream order received in real time, mitigating instability for domain switch and overmemorization for the recent domain data.
A Domain Expert Framework: A shared expert learns a unified representation across all domains, while domain-specific experts capture surface-specific patterns. Each domain expert benefits from both: the shared cross-domain knowledge and its own specialized knowledge. Experts are built on top of the Kunlun architecture framework.
Training a RecSys Model at LLM-Scale Efficiently
GEM now trains at LLM scale on several thousand of the latest-generation GPUs. Today’s data center GPUs and their software stacks are mostly optimized for LLM workloads, whereas recommendation workloads have a fundamentally different profile due to unique data characteristics and rich user & ads signal interaction patterns that make it extremely difficult to achieve high GPU compute utilization for training a foundational recommendation model of GEM’s size.
We measure training efficiency through E2E MFU, which decomposes into two factors: E2E MFU = Local MFU (compute efficiency) × Scaling Ratio (scaling efficiency). Local MFU (compute efficiency) measures how well a single GPU’s compute units are utilized — how close the workload runs to the hardware roofline. Scaling Ratio (scaling efficiency) measures how much single-GPU performance is retained when distributing across thousands of GPUs. This decomposition matters because it lets us treat compute efficiency and scaling efficiency as related but distinct optimization problems, each with its own dedicated set of techniques. Both must be addressed to maximize end-to-end MFU.
We tackled these challenges through complementary compute efficiency and scaling efficiency innovations:
- Compute efficiency: Achieved through a customized recommendation kernel library — Jagged Flash Attention (JFA), GDPA, Block-Attention, etc. — and mixed ultra-low precision training (including MXFP8 attention and MLP) optimized for recommendation workloads, purpose-built to leverage the latest generation GPU architecture.
- Scaling efficiency: Topology-aware 5D parallelism with Streaming Multiprocessor (SM)-free collectives — 2D FSDP + Expert Parallelism for dense parameters, combined with Fully Sharded 2D Model Parallelism for sparse parameters — co-designed with Meta’s multi-tiered network hierarchy to reduce communication overhead.
The result: We doubled GEM’s E2E training efficiency to 20-25% MFU over the past 12 months while scaling total training FLOPs by 4x. Training a foundation model at the intersection of LLMs and recommendation systems is a co-design problem, not a software problem or a hardware problem alone. This 2x efficiency gain came from carefully considering every layer of the stack for optimization — kernels, precision, parallelism, networking, and memory all had to move together.
For the full technical story, see our companion blog: GEM Training: Train Meta’s LLM-Scale Ads Recommendation Model Efficiently.
The Future of RecSys Foundation Models
Looking forward, we are excited to extend GEM to learn from all of Meta’s platform data, capturing behavior across organic and ads engagements spanning text, images, and video. We’re building toward LLM-scale long context, giving the model the ability to reason over longer spans of engagement context. This will unlock better ad relevance and help advertisers connect with the right audiences more efficiently.
We will continue to scale GEM on even larger compute clusters, opening new scaling opportunities. We are introducing AI-driven optimizations, such as ecosystem enhancement and architecture co-design, to accelerate future evolutions. These optimizations will iteratively refine model architecture in lockstep with hardware advancements, so that each new generation delivers more intelligence per dollar of compute. We will evolve the post-training paradigm with reasoning capability to transfer more of this intelligence to downstream models, further improving advertiser performance and user experience.
Acknowledgements
We would like to thank Laming Chen, Yasmine Badr, Shali Jiang, Hua Zheng, Boyang Liu, Qianru Li, Zhengyu Zhang, Xiaozhen Xia, Angie Huang, Xiaolong Liu, Dan Chanpuriya, Jason Rudy, Cathy Cui, Kenny Lov, Qiuling Suo, Richard Qiu, Wentao Duan, Habiya Beg, Sandor Abad, Amit Anand Amlesahwaram, Carmen Au, Balaji Balasubramanian, Ayush Bihani, John Bocharov, Raghav Boinepalli, Bopa Bovet, Mandeep Chadha, Shuo Chang, Hansey Chen, Ping Chen, Ruilin Chen, Wenlin Chen, Xian Chen, Jae-Woo Choi, Sagar Chordia, Yan Deng, Lisang Ding, Eric Falconer, Qi Fan, Xiaorui Gan, Nikhil Garg, Chenxiao Guan, Saket Gur, Brian Hansen, Rustam Hashimov, Bingjie He, Jack Hsueh, Yusuo Hu, Qin Huang, Yuzhen Huang, Subodh Iyengar, Qinjin Jia, Qiang Jin, Pawel Kadluczka, Donghyun Kim, Santanu Kolay, Hairong Kuang, Peter Lamar, Seunghan Lee, Max Leung, Jazlyn Li, Mingda Li, Chen Liang, Haowen Lin, Wei Ling, Rocky Liu, Serena Liu, Xi Liu, Xin Liu, Zikun Liu, Hank Lo, Anuj Madan, Shuby Mao, Paolo Massimi, Santosh Mohan, GP Musumeci, Jade Nie, Enes Palaz, Ke Pan, Sandeep Pandey, Jerry Peng, Tianshu Peng, Patrick Phelps, Oana Platon, Damian Reeves, Purbesh Sahoo, Ke Sang, Rikin Shah, Jingyi Shen, Min Si, Vibha Sinha, Jake Siso, Matt Steiner, Bor-Yiing Su, Anamaya Sullerey, Musharaf Sultan, Chonglin Sun, Vivienne Sung, Kevin Tang, Robert Tang, James Teng, Ritwik Tewari, Lei Tian, Sandeep Tiwari, Viral Vimawala, Ernest Wang, Kai Wang, May Wang, Zhaojin Wen, Rupert Wu, Huaqing Xiong, Han Xu, Ivonne Xu, Jiayi Xu, Liangbei Xu, Hao Yan, Tak Yan, Angel Yang, Fan Yang, Jiyan Yang, Justin Yang, Wen-Chi Yang, Hongtao Yu, Li Yu, Zhichen Zeng, Hanbin Zhang, Jiasheng Zhang, Larry Zhang, Lei Zhang, Feipeng Zhao, Qian Zhao, Jie Zheng, Peng Zhong, Jacky Zhou, Qinghai Zhou, Song Zhou, Zhehui Zhou, Rich Zhu, Wankun Zhu, Devashish Shankar and the entire team behind the development and productionization of the largest foundation model in Meta’s ads recommendation system.