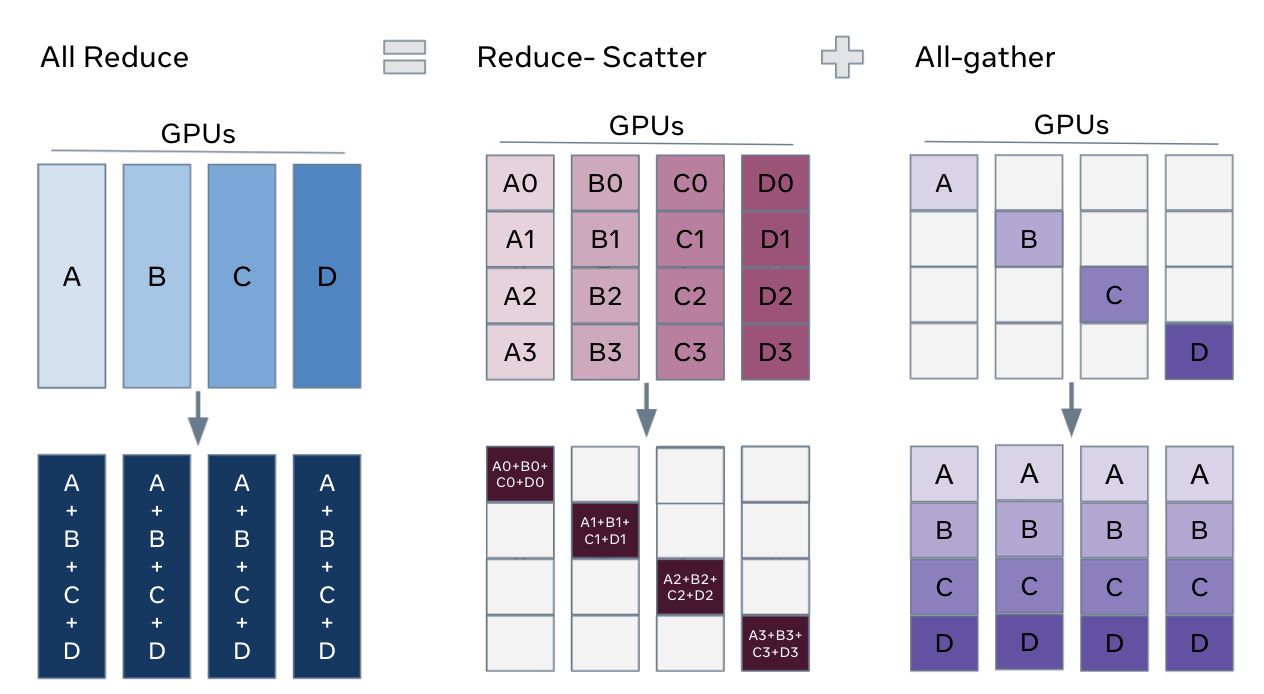
All-reduce as a combination of reduce-scatter and all-gather. The standard all-reduce operation to aggregate gradients can be decomposed into two separate phases: reduce-scatter and all-gather. During the reduce-scatter phase, the gradients are summed in equal blocks among ranks on each GPU based on their rank index. During the all-gather phase, the sharded portion of aggregated gradients available on each GPU are made available to all GPUs (see here for details on those operators).
All-reduce as a combination of reduce-scatter and all-gather. The standard all-reduce operation to aggregate gradients can be decomposed into two separate phases: reduce-scatter and all-gather. During the reduce-scatter phase, the gradients are summed in equal blocks among ranks on each GPU based on their rank index. During the all-gather phase, the sharded portion of aggregated gradients available on each GPU are made available to all GPUs (see here for details on those operators).
Meta believes in building community through open source technology. Explore our latest projects in Artificial Intelligence, Data Infrastructure, Development Tools, Front End, Languages, Platforms, Security, Virtual Reality, and more.
ANDROID
iOS
WEB
BACKEND
HARDWARE
Allow the use of cookies by Meta on this browser?
We (Meta Platforms Ireland Limited) use cookies on this site. Some of these are essential cookies which are required for the site to work as intended. We also use optional cookies to perform site analytics and measure the performance of content on this site. You have control over the optional cookies that we use. If you choose to "Decline optional cookies", you can continue to use the site but we will be unable to perform site analytics on this site using such cookies and similar technologies. Learn more about our cookies and third-party providers in our Cookies Notice, or you can review or change your choices, including withdraw your consent, at any time in your Settings page.