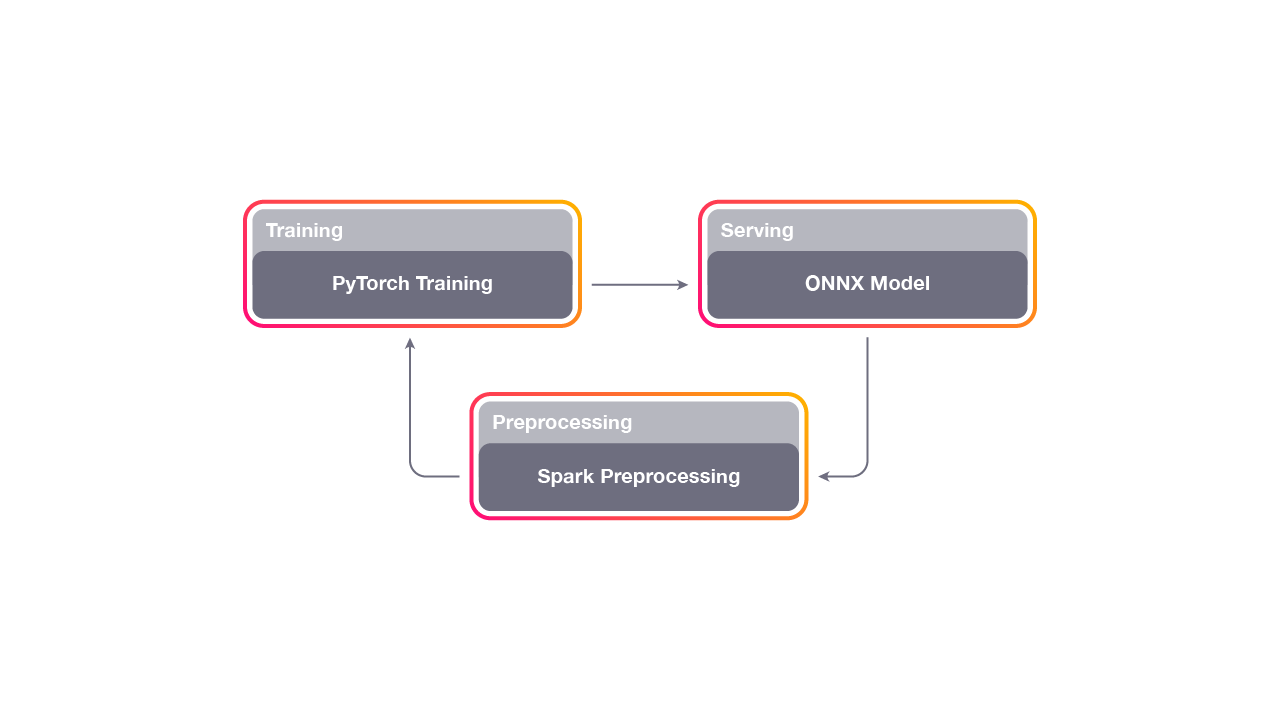
This high-level diagram explains the feedback loop for Horizon. First, we preprocess some data that the existing system has logged. Then, we train a model and analyze the counterfactual policy results in an offline setting. Finally, we deploy the model to a group of people and measure the true policy. The data from the new model feeds back into the next iteration, and most teams deploy a new model daily.
This high-level diagram explains the feedback loop for Horizon. First, we preprocess some data that the existing system has logged. Then, we train a model and analyze the counterfactual policy results in an offline setting. Finally, we deploy the model to a group of people and measure the true policy. The data from the new model feeds back into the next iteration, and most teams deploy a new model daily.
Meta believes in building community through open source technology. Explore our latest projects in Artificial Intelligence, Data Infrastructure, Development Tools, Front End, Languages, Platforms, Security, Virtual Reality, and more.
ANDROID
iOS
WEB
BACKEND
HARDWARE
Allow the use of cookies by Meta on this browser?
We (Meta Platforms Ireland Limited) use cookies on this site. Some of these are essential cookies which are required for the site to work as intended. We also use optional cookies to perform site analytics and measure the performance of content on this site. You have control over the optional cookies that we use. If you choose to "Decline optional cookies", you can continue to use the site but we will be unable to perform site analytics on this site using such cookies and similar technologies. Learn more about our cookies and third-party providers in our Cookies Notice, or you can review or change your choices, including withdraw your consent, at any time in your Settings page.